
Home
Where SSIM stops measuring what you think it measures — proven in closed form, verified at scale
We believe science should be honest. Showing everything in a form that can be verified — not just the convenient results, but our mistakes too — is why open science resonated with us, and it's where Meritcs (/ˈmɛrɪtɪks/) starts.
When can a metric like SSIM (the Structural Similarity Index) be trusted, and when does it stop being trustworthy? We keep testing that boundary, painstakingly, block by block — through closed-form mathematical proof and tens of millions of real image blocks alike.
Our goal is not to rank specific models, but to establish a reproducible methodology for using these metrics correctly, and to publish that methodology in a form anyone can independently verify.
Why this matters
Image-quality metrics like SSIM are used everywhere models are evaluated — from AI upscaling to medical imaging pipelines. When a metric can be gamed, or silently breaks down, every benchmark built on top of it inherits that blind spot: a model can look like it's performing well while it's actually failing in ways nobody catches. That's why it matters.
What this makes possible
At the core of this method is the ability to diagnose a model's behavior using only the input/output image statistics that can be observed from the outside — without any access to the model's internals (training data, architecture, or weights). Testing several independently-trained models with the same method, we've confirmed that both how a model behaves in regions where the metric structurally breaks down, and how faithfully it reconstructs the ground truth, vary from model to model (see the publications list for details).
We see practical potential in this "external diagnosis" property — evaluating third-party models you can't access internally, detecting behavioral drift when a model is updated, and independent verification in high-stakes domains like medical imaging are among the directions we expect this to extend toward.
Selected findings
- A closed-form derivation of exactly where SSIM's score stops reflecting reconstruction quality
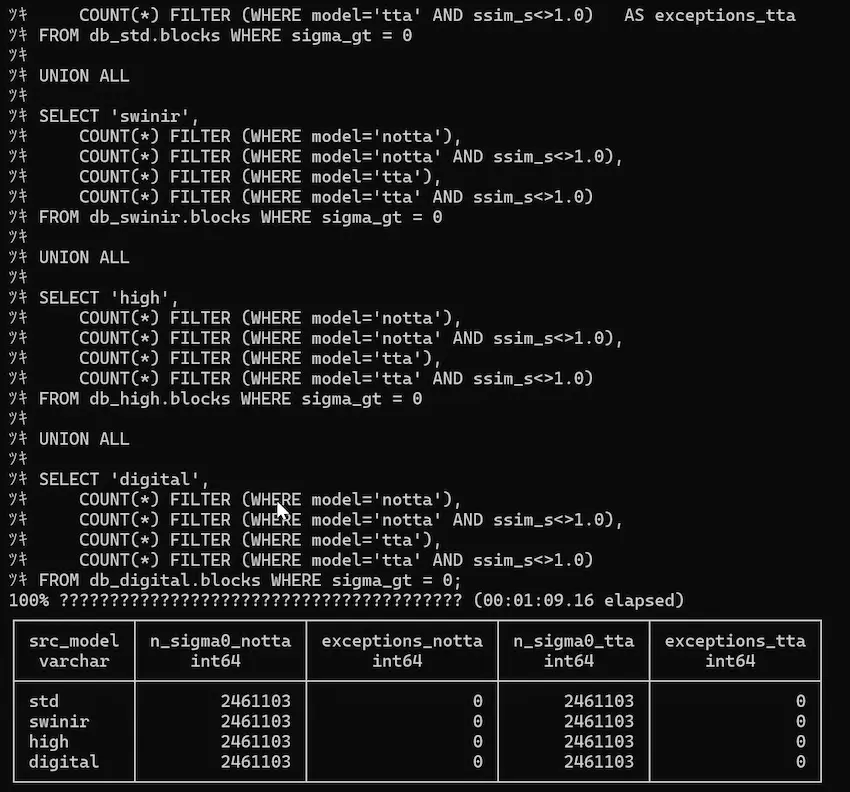
- A proven "masking blind spot": flat regions where the metric is mathematically forced toward a perfect score, regardless of content (σgt = 0 ⇒ S = 1)
- Empirical evidence, across four independently trained models, that no single diagnostic — SSIM or auxiliary feature checks alone — is sufficient on its own
What's new
Explore the site
Publications
The technical report series (DOI 1.0–1.21) and a correction trail documenting past errors and their fixes.
Documentation
Plain-language walkthroughs of every verification SQL query and the pipeline code behind it.
Demonstrations
Screen-recorded videos of the 3D block viewer, 2D heatmap viewer, and SQL verification running live.
Technology
The dataset, the four AI models, and the database pipeline behind every result.
About
Who's behind this research, and how it started.